

I need to fix the four known errors and check all other claims against FACTS.
**Known errors to fix:**
1. S4b gate wrongly says “face-time share in 8-20% band required” , S4b gate is “plan dry-render PASS before lip-sync”. The 8-20% split-screen share is checked by ATTEST at publish.
2. S10 compose wrongly includes stat cards timed to captions, drift >2s hard fail, and pixel probing , those belong to PushPoint post-processor, not PushVid AI compose.
3. S2 “Credit preflight before each request” , preflight of balances happens at S0, not S2. Also S6 “md5 matches backup” as a gate , plates are backed up with md5 checks but this isn’t listed as a stage gate in FACTS.
4. RunPod “7 days” language , it’s “last 10 takes” not “7 days.”
Also checking: The all-in cost table says “10 published videos” but FACTS says 14 delivered, 12 first-pass , the $9.83 figure comes from $98.35 / 10 implied, but FACTS says “7 days $98.35” and “$9.83 per published video.” I’ll keep $9.83 as stated in FACTS without specifying “10 published videos” since FACTS doesn’t explicitly state that denominator.
Also: “75-second chunk at 30 fps” , LatentSync outputs 25 fps, input chunks are from the plate (which is 30fps but the chunk math given in FACTS is based on ~6.2 MB per 1080p frame, 75s, ~11GB). The article says “75-second chunk at 30 fps = 2,250 frames” but LatentSync outputs 25fps and the plate is 30fps. FACTS just says “~6.2 MB per 1080p frame, so 75 s is ~11 GB” without specifying which fps for the RAM calculation. I’ll remove the explicit fps-based frame count since FACTS doesn’t give it, and just state what FACTS states.
Also checking the Lip-Sync section: “A 10-minute video = ~9 chunks = ~3.3 hours workstation-only” , FACTS says wall time up to ~5 hours on workstation alone, and ~9 chunks. The article’s “~3.3 hours” is not in FACTS (9 chunks × 22 min = 198 min = 3.3 hours is arithmetic, but FACTS explicitly says “up to ~5 hours on the workstation alone”). I’ll use the FACTS figure.
This page is the primary technical reference for the three automated video pipelines PushLeads runs internally: PushPoint, PushVid AI, and PushVid. All numbers come from our internal documentation dated October 27, 2026. The system turns a topic into a published YouTube video plus a matching web page with chapters, a transcript, and VideoObject schema, at a production cost of roughly $1-$2 per slideshow video and $9.83 all-in per published PushVid AI video once supervision and automated fixes are counted (our data). A rebuild is a port of a codebase and a data model, not a translation of workflow nodes.
0:00 Intro
1:32 The Platform: Not What You Think
2:26 The Infrastructure Stack
3:16 PushPoint: the Narrated Slideshow Pipeline
4:55 The Embed Block and Page Publishing
6:21 Lip-Sync: LatentSync on the Take
7:23 The Spend Breaker and GPU Supervision
9:17 Approval and Publishing
9:55 What It Actually Costs
10:45 Weak Spots: What Doesn’t Work Well
11:23 Supervision: the Cost of Keeping It Running
12:42 The Module Map for a Rebuild
Full transcript
0:00 Intro
Before I say anything else, I want to be straight with you. The voice you’re hearing right now is not me recording in a studio. It’s my 11 -labs voice clone. The mouth movement you’re watching is AI -generated lip sync running on a recorded plate of me. This video is itself made by the system it describes. That’s not a disclaimer to rush past, it’s the whole point of what we built. A topic goes in. A published YouTube video with chapters, captions, a transcript, and a matching webpage comes out about $4 in production cost. Here’s exactly how it works. PushLeads runs three automated pipelines. Pushpoint, a fully automated narrated slideshow. 209 videos classified as slideshows so far. Marginal costs about $1 to $2 per 10 -minute video. Pushvid, a long -form talking head format built from a real recording of me, composed with deck panels, charts, and b -roll. Pushvid AI, internally called PushPro AI, same long -form format, but instead of a real recording, the voice is my 11 -labs clone, and the mouth is re -synced onto a pre -recorded plate of me. In the last seven days, Pushvid AI delivered 14 -14 production videos, 12 passed on first attempt, an 86% first pass rate, Q2 -finished file, roughly three hours, all in published costs, $9.83 per video, once you count supervision and automated fix -up, that number matters.
1:32 The Platform: Not What You Think
If you picture an N8N workflow with hundreds of nodes, stop. N8N is only the front door. It’s a webhook router with auth, rate limits, and an audit log. The real system is about 190 JavaScript and Python drivers. Stored is text and Postgres, a rebuild is a port of a codebase and a data model, not a Drivers are async, JavaScript functions stored as text, a caller loads one, evals it, calls it with a parameter object. Python helpers are stored the same way and written to disk before running. Every long pipeline is a resumable state machine. State is check pointed in one key per run. Each call works until a time budget runs out, saves and returns pending true with the current stage. A crash resumes from the last past gate. The orchestration host runs Linux with Docker and about 19 containers.
2:26 The Infrastructure Stack
It has eight cores and no GPU. That machine handles orchestration, slideshow builds, audio mastering, and delivery. Pushbeast is my Windows workstation with an RTX 3090. That card carries 24 gigabytes of VRAM. Pushbeast handles latent sync, 1.6 lip sync and mouth composite. It also runs self -hosted TTS and STT. I use that machine personally, so a policy key controls rendering. The key simply turns rendering on or off as needed. Rented GPUs come from vast .i RTX 5,090 pods. Vast handled all 19 successful rents without issue. External services include Anthropic’s Claude and 11 labs. The stack also uses YouTube data API version 3. That API runs across three Google Cloud projects.
3:16 PushPoint: the Narrated Slideshow Pipeline
The topic director runs on Sundays. It pulls search console queries, long queries over 55 characters as an AI search signal, AI overview citation records, a YouTube channel scan, and data for SEO search checks capped at $1 per run. The scoring formula, AI impressions times 2 plus AI keywords times 12. Buyer intent terms like cost, price, worth it, vs. near me, get a four times boost. Guards before any topic enters the queue. Pages with pending changes are excluded, pages that already have a video or skipped, fuzzy duplicate check on keyword jacquard above 0.8, home and contact pages never touched, and no new topics if the render runway is already over seven days. Then, Claude Sonnet expands the page or writes a new 3,000 to 5 ,000 word page with two AI images, FAQ schema, article schema, and a video slot marker. Sonnet writes a slide -cued voiceover and deck spec in one of 25 format variants. That matters because YouTube’s inauthentic content policy targets sameness, not volume. The rule here is critical, never synthesize the whole script and a line afterward. A single cut would desync every later slide. One narration segment per slide, period, every encode carries a square pixel flag, and the build fails unless the output is exactly 1920×1080 square pixels. LibreOffice output carries a slightly non -square pixel aspect that FFmpeg will honor silently.
4:55 The Embed Block and Page Publishing
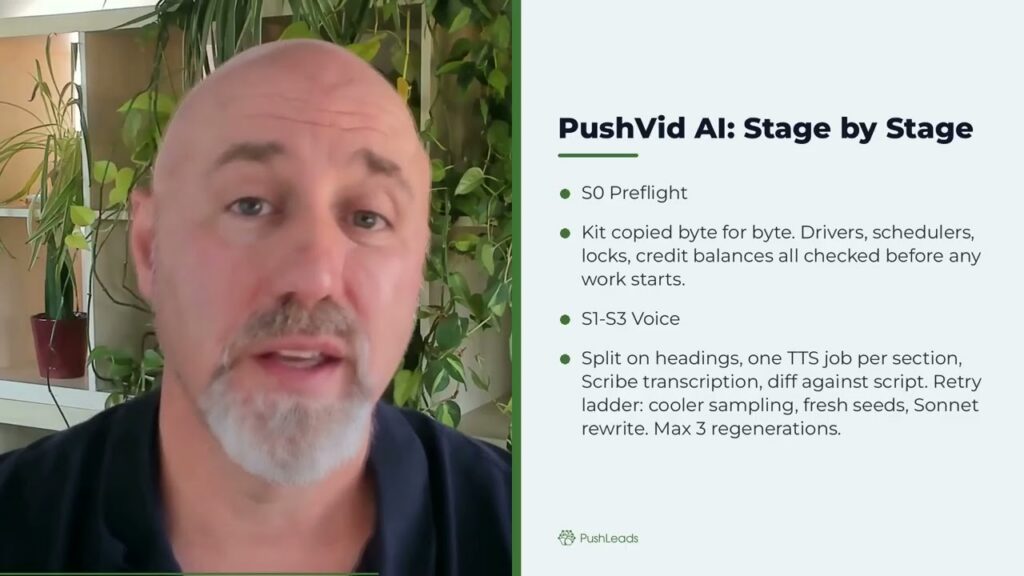
The embed block is a pure function, no network calls, no database calls, old video objects for the same video are removed before the new one is inserted. After upload the system reads back the live page and verifies the video ID is present. That verification is a hard gate, not a courtesy check. This is the pipeline that made this video. Stage zero, the kit is copied byte for byte before anything reads it. Pre -flight checks, drivers, schedulers, locks, credit balances, stage one, split the script on headings, section count must match sections, JSON exactly. Stage two, one TTS job per section, saved as it lands. Stage three, whole section transcription with 11 -lab scribe, the retry ladder, cooler sampling first, then fresh seeds, then one sonnet rewrite, maximum three regenerations, then escalate. The gate, no inserted or dropped run of two or more words, plus a static and noise floor check. Why per section rather than per sentence? Per sentence checks miss defects that land on sentence boundaries. The diff has to cover the full section. You get a full quality audio track and a 16 kilohertz mono drive track. Stage four B, build and dry render the composition plan before lip sync. Plan errors fail before GPU money is spent. That gate order matters.
6:21 Lip-Sync: LatentSync on the Take
The plate is one continuous recording of me, about 15 minutes, no cuts, no black frames, at 1080p 30, with eye contact correction done once in descript latent sync 1.6, the stage two 512 config, 20 inference steps, deep cache output at 25 fps, a 10 minute video is about 9 chunks. On the RTX 3090, a 72nd chunk takes roughly 22 minutes and peaks, near 21 to 24 GB of VRM. Voice models in lip sync can never share the card, a binding GPU lease enforces one model at a time. Failing hosts are destroyed and avoided, listing failures throw instead of returning an empty list. And here’s a lesson that costs real money, never default a failed remote list to empty before a safety decision. An API change once made a billing GPU pod look like nothing running, rent -hunting costs 10 to 20 minutes per take, wall time per take, roughly 57 minutes with three pods, up to five hours on the workstation alone.
7:23 The Spend Breaker and GPU Supervision
The spendbreaker runs every five minutes, each take is capped at $3 per take, the daily run limit is 12 per day, the daily spend ceiling is $10 the hourly ceiling is 8 per hour, pod minutes are capped at 120, provider balance floors also act as limits, a trip destroys pods and pauses the resumer, an orphan pod sweep also runs every five minutes, destroy calls have silently failed before, the breaker and the sweep together form the backstop, the composition plan is built in 152 windows, it draws from the deck, transcript and layout catalog that catalog contains 23 layouts in total, each FFmpeg chunk line is hashed and cashed and unchanged revision renders in roughly three minutes, a fresh 10 minute video takes about nine minutes of machine time, audio is mastered to negative 14 LUFS, no video publishes without passing all eight, one content gate, two were diff, the final audio transcribed and diffed against fail closed process attestation, required stages ran, every render node produced its chunks, split screen share is between 8 and 20%, b -roll is on topic judged by vision tags, no retake slivers in the output, five visual review, a vision model sampling frames for blank text, garbled numbers and frozen frames, six, restate gate checking for false start restatements, seven, pro vid QC plan quality, including face time share, eight frame verify every single frame decodes, run these gates before the expensive steps wherever possible, the claim gate runs before any TTS is bought, the plan gate runs before lip sync fail closed always. When every gate is green,
9:17 Approval and Publishing
AI videos publish automatically, maximum two per day, one key turns autopilot off, anything not green waits for a WhatsApp message, reply yes, approve or go, and it releases a change note becomes fixed settings and triggers a rerender under a new video ID, the publisher refuses to run without either an approval record or an autopilot pass, it refuses a second approval of the same ID, it never marks a video as published unless YouTube returned a video ID, every external right is idempotent behind a publish lock and verified by reading it back. That pattern applies everywhere uploads and beds schema injection,
9:55 What It Actually Costs
push point, a nine minute 24 second video measured at 9,022 characters, which is 4 ,511 11 labs credits costing about 74 cents in TTS at the pro plan rate, push vid AI production costs roughly $4, all in published cost over seven days $9.83 per video, that breaks down as GPU $18.98, supervision and fixing were 61% of the total cost, that number tells you where to invest in a rebuild, a supervision cap introduced on October 24 cuts the Mac share going forward, 11 labs pro at $99 per month give 600,000 credits, enough for roughly 130 10 minute turbo videos, real
10:45 Weak Spots: What Doesn’t Work Well
recording intake regression tests zero out of 10 in the last seven days, that is the least reliable part of the system, midward restarts are not cut by the current filler removal pass, FaceTime share varies run to run because the shop plan is not deterministic, GPU supply, run pod zero for 114, vast destroy calls have silently failed before the mouth composite has no automatic retry failed render chunks are relaunched by index, workstation availability varies daily, because I actually use that machine, resume every five minutes max the lm operator agent handles states with no rule,
11:23 Supervision: the Cost of Keeping It Running
capped at $3 per day, all in and 150 per run, an automated cloud fixer with shell access runs after three failed attempts, or 20 minutes stuck, a deterministic rule engine is planned to replace most of the LLM deciders, and LLM acting as operator or engineer does not belong in the product version. One narration segment per slide one TTS job per voice section, never synthesize a full script and align afterward, transcribed generated audio and diff per section, per sentence checks miss boundary defects, check file size and decode every frame, a 54 by mp4 is not a video, probe sample aspect ratio, codec, FPS and audio parameters before concatenation, mismatched segments are dropped without an error by FFmpeg, never default a failed remote list to empty before a safety decision, run gates before the expensive step, make them fail closed, every external right idempotent behind a published lock verified by reading it back, one owner per run, one writer per state key, budgets per take per run per day per hour, with self expiring overrides. Here are the modules any rebuild needs to cover, a durable workflow engine with
12:42 The Module Map for a Rebuild
resumable steps, retries by failure class, and timers, tenant and lane configuration, content services, topic scoring, page writer, kit writer, page matcher, media workers, deck render, TTS, slide show assembly, composition render, GPU job service with provider adapters, leases, qualification and budgets, a gate library as pure functions with recorded verdicts, publish adapters, YouTube, WordPress, LinkedIn, drive, approvals and notifications, cost ledger and measurement, admin UI, the path to a product from this system means replacing per client code forks with forms and connection wizards, replacing handwired tokens with OAuth flows and keeping hard spend limits checked before every paid step per video inputs, type, topic, fact source, length, CTA date, one time setup, brand kit, voice, presenter plate, approval mode, an LLM acting as operator costs real money and introduces unpredictability at scale, a rebuild should make the rules explicit and let the LLM handle only the edge cases it genuinely cannot avoid. That’s the system topic in published video out, no magic, just a lot of gates. If you want to see what this approach does for search visibility, get a free visibility teardown at SEO .PushLeads .com slash audit or call 828 -348 -7686
The 15-minute walkthrough above is itself a PushVid AI video: narrated by my ElevenLabs voice clone, lip-synced onto a recorded plate of me using LatentSync 1.6, and published by the same pipeline this page describes.
The Three Pipelines
Every pipeline shares the same orchestration host, database, and publish layer. What differs is where the presenter “take” comes from: synthesized narration over slides, cloned voice plus lip-sync onto a recorded plate, or a real camera recording composed with deck panels and b-roll.
| Pipeline | Presenter | What it produces | Status and numbers (our data, Oct 27 2026) |
|---|---|---|---|
| PushPoint (formerly PushVid v1) | AI-narrated branded slide deck; no live presenter | 1920×1080 MP4 slideshow, ElevenLabs narration per slide, captions, YouTube upload, WordPress embed with VideoObject schema | 209 videos classified as slideshows; fully automatic; marginal cost ~$1-$2 per 10-minute video; 5 render slots per day; 184 queue rows: 117 done, 5 queued, 3 running, 24 blocked, 21 parked, 10 superseded, 4 failed |
| PushVid AI (internally PushPro AI) | Jeremy’s ElevenLabs voice clone; mouth re-synced onto a pre-recorded plate via LatentSync 1.6 | Long-form talking-head MP4, composed with deck panels, charts, b-roll, lower thirds, chapters, captions; YouTube and WordPress publish; LinkedIn queue | 7 days to Oct 26: 14 of 14 production videos delivered; 12 first-pass (86%); ~3 hours queue to finished file; ~$4 production cost; $9.83 per published video all-in; publishes without human approval (max 2/day) when all eight gates pass |
| PushVid (formerly PushVid v2) | Real recording of Jeremy with deck panels, charts, b-roll | Same composition and publish layer as PushVid AI; intake differs | Intake regression test passed 0 of 10 times in the last 7 days (our data); still requires Jeremy to record and approve; real-recording intake is the least reliable part of the whole system |
Platform Architecture
Most logic does not live in n8n. n8n is only the HTTP front door: a webhook router with auth, per-consumer rate limits (60 to 600 requests per minute, our data), and an audit log. The roughly 190 JavaScript and Python drivers that do the actual work are stored as text in Postgres and executed by a Node.js sidecar. A rebuild means porting that codebase and data model.
| Component | Role | Detail (our data) |
|---|---|---|
| Orchestration host | Linux VPS, Docker, ~19 containers | 8 cores, no GPU; handles orchestration, slideshow builds, part of ffmpeg render, audio mastering, delivery |
| n8n (queue mode) | Webhook router only | 4 workers; consumer API keys; routing logic is itself a hot-reloaded driver |
| Node.js execution service | Runs driver code | Node 20 sidecar; warm worker pool; job table with cancel and poll endpoints; driver cache with hot reload; 1-hour job cap; changes ship through a gate script with test, promote, and automatic rollback |
| Postgres | Single source of truth | Brain key-value table (driver code, config, per-run state, logs, with history) plus relational tables for queues, kits, videos, costs, jobs, locks |
| Scheduler | ~45 scheduled jobs | Rows with a cron expression plus a script; ticks from every 1 minute to weekly |
| Dashboard | Next.js on Vercel | Deployed from GitHub; PushVid tab shows run heartbeats, locks, items needing a human; costs and alerts |
| PushBeast workstation | RTX 3090 24 GB | LatentSync, mouth composite, self-hosted TTS and STT; shared with Jeremy’s own use; a policy key turns rendering on or off |
| Rented GPU pods | Vast.ai RTX 5090 (primary); RunPod configured but rarely has capacity | Last 10 takes: RunPod returned no capacity on all 114 attempts; Vast made all 19 successful rents (our data); rent hunting costs 10-20 minutes per take |
| Render fleet | Distributed ffmpeg chunk render | ~28 cores across 4 machines; work stealing from slow nodes |
| Anthropic Claude | Pages, scripts, kits, shot director, vision checks | Sonnet for pages/scripts/kits/page matching/rewrites; Haiku for triage; a larger Claude model for the shot director; web_fetch server tool to digest live pages |
| ElevenLabs | TTS and STT | eleven_turbo_v2_5 default; multilingual_v2 optional; Scribe for speech-to-text with word timings; subscription endpoint for credit preflight; Pro plan $99/month = 600,000 credits (~130 ten-minute turbo videos) |
| YouTube Data API v3 | Upload, captions, thumbnails, privacy | Quota spread over 3 Google Cloud projects; ~14 uploads per day |
| Image and video generation | fal.ai (images and Veo b-roll), Gemini, Pollinations (last fallback), Pexels stock | Veo via fal ~$0.10/second, capped $6/video (our data) |
| Other external services | Descript, Vast.ai, RunPod, DataForSEO, Twilio WhatsApp, LinkedIn, HeyGen (optional) | Descript polled (no webhooks); DataForSEO SERP checks capped at $1/run; WhatsApp for approval messages only |
Execution Model
Drivers are async JavaScript functions stored as text. A caller loads one, evals it, and calls it with a parameter object. Python helpers are stored the same way and written to disk before running. Four properties must be preserved in any rebuild.
Resumable state machine. Every long pipeline checkpoints its state in one key per run in the Brain table. Each call works until a time budget runs out (40 minutes default for PushVid AI), saves state, and returns pending:true with the current stage. A scheduler tick calls it again. Every step is skip-if-done, so a crash resumes from the last passed gate.
Detached GPU work. GPU and render work is launched detached and polled with short jobs that read result files. A 70-second LatentSync chunk on the RTX 3090 takes ~22 minutes (our data); no caller can wait that long. Long host commands are killed at ~300 seconds, so work that outlasts that window is launched detached via a small host exec service that also runs ffmpeg, LibreOffice, and Python on the host.
Idempotent artefacts. Inputs are copied before use and never modified. Every stage writes a new artefact. Any stage can be re-run alone. Each ffmpeg chunk line is hashed and cached: an unchanged revision renders in ~3 minutes; a fresh 10-minute video takes ~9 minutes of machine time (our data).
Concurrency controls. Per-slug locks; publish locks keyed on asset and platform; a per-run publisher mutex; a binding GPU lease so only one model loads on the 24 GB card at a time; the rule that a live run belongs to the pipeline and humans or agents act only through a bounded “medic” driver or a hold.
Change control. Backup copy before any driver edit; anchored string replacements plus a parse check; two test gates (dry run, then a live run on real data). In 7 days to Oct 26 we made 128 driver edits across 52 drivers (our data), which is exactly the kind of churn that a product version of this system should eliminate by moving to versioned deploys.
PushPoint Stages and Gates
| Stage | What happens | Gate / hard-fail condition |
|---|---|---|
| Topic director (Sundays) | Scores pages by Search Console demand, long queries (>55 chars as AI-search signal), AI Overview citation records, YouTube channel scan, DataForSEO SERP check | Guards: pages with pending changes excluded; URL clusters deduped; pages with a video skipped; fuzzy duplicate check (keyword Jaccard 0.8+); home/about/contact/main service pages never expanded; no new topics while render runway exceeds 7 days |
| Page expand | Claude Sonnet expands the page in place or writes a new 3,000-5,000 word page with two AI images, FAQ, and Article schema, published to WordPress with a VIDEO_SLOT marker | Content at least 2,800 words else hard fail; answer-first structure (40-word direct answer, FAQ, named entities, numbers); VIDEO_SLOT marker read back from the live page |
| Script and deck spec | Sonnet writes a slide-cued voice-over and deck spec in one of 25 format variants (7-24 slides, ~4-14 min); variant seeded on the slug with an FNV-1a hash so resumes get the same variant | Words within variant max plus 60 else a compression pass; segment count must equal slide count |
| Deck render | Per-brand PPTX renderer (palette, fonts, logo, 13 slide types plus bio slide); LibreOffice + pdftoppm to PNG | Exactly 1920×1080 at SAR 1:1; build fails unless square pixels (LibreOffice output carries a slightly non-square pixel aspect that ffmpeg honours, so setsar=1 is explicit in every encode) |
| TTS per slide | One ElevenLabs request per slide; each slide lasts as long as its narration plus a pad; captions from character-level alignment grouped at 42 chars or fewer on sentence boundaries | Runner refuses to start under 20,000 ElevenLabs credits; never narrate the whole script and align afterwards (a single cut would desync every later slide) |
| Slideshow encode | 1920×1080 MP4 assembled; optional avatar bubble placed by ink-detection search for empty slide area | Idempotent, skip-if-exists; one automatic retry; file size and frame decode check |
| YouTube upload | Title, description, chapters, tags, captions; LinkedIn post queued | Video id returned and verified; video id read back from live page |
| Embed inject | Embed block (lazy responsive iframe, chapter deep links, collapsible transcript, VideoObject JSON-LD with hasPart Clip entries and SeekToAction) inserted into WordPress page; old VideoObjects for the same video removed before insert | Embed verified by re-reading the live page; chapters need at least 3 entries 10 seconds apart |
| Measurement | 28-day pre and post windows on Search Console; weekly AI-citation prompts | No gate; passive tracking only |
PushVid AI Stages S0-S10 and Gates
The composition plan is built and dry-rendered before lip-sync starts (S4b). That single ordering decision means plan errors fail before GPU money is spent, the most important scheduling rule in the whole pipeline.
| Stage | Label | What happens | Gate |
|---|---|---|---|
| S0 | Preflight | Kit copied byte for byte before anything reads it; preflight of drivers, schedulers, locks, balances | All drivers present; no active lock for this slug; ElevenLabs and provider balances above floor |
| S1 | Split | Script split on headings into sections | Section count must match sections.json exactly |
| S2 | TTS | One TTS job per section, saved as it lands; text normalised for speech (e.g. “SEO” becomes “S-E-O”); self-hosted Chatterbox engine available as alternative | Saved file size check; idempotent (skip if file exists) |
| S3 | Transcribe and diff | Whole-section transcription with ElevenLabs Scribe; normalised in cardinal and digit modes; diffed against script; retry ladder: cooler sampling, fresh seeds, one Sonnet rewrite; max 3 regenerations then escalate | No inserted or dropped run of 2+ words; static and noise check; bad sections regenerated before continuing |
| S4 | Audio concat | Sections joined with room tone at -62 dBFS between segments (digital silence freezes the LatentSync mouth); full-quality track plus 16 kHz mono drive track produced | Full-quality and drive tracks both present and decodable; duration within expected bounds |
| S4b | Plan and dry render | LLM director plans shots in 150-second windows from deck, transcript, and a catalog of 23 layouts; plan dry-rendered before lip-sync is started | Plan dry-render must pass before any GPU spend; plan errors fail here |
| S5 | GPU free | Voice models unloaded; binding GPU lease acquired | Lease confirmed; one model at a time on 24 GB card |
| S6 | Plate pick | Plate (continuous ~15-minute 1080p30 recording of Jeremy, eye-contact corrected, no cuts, no black frames) selected least-recently-used by wardrobe; plates backed up with md5 checks | Plate file decodes; no black frames |
| S7 | Lip-sync chunks | LatentSync 1.6, stage2_512, 20 inference steps, DeepCache, output 25 fps; chunks capped at 75 seconds (~11 GB RAM per chunk at ~6.2 MB per 1080p frame); ~9 chunks per 10-minute video; Take Controller v2 assigns chunks every 2 minutes across workstation and rented pods; policy: workstation plus 3 rented GPUs per 10 minutes of voice; pods qualified by measuring real download speed and CUDA; failing hosts destroyed and avoided; listing failures throw instead of returning an empty list; wall time ~57 minutes with 3 pods, up to ~5 hours workstation-only (our data) | Spend breaker checked every 5 minutes ($3/take, $12/run/day, $10/day, $8/hour, 120 pod-minutes); orphan pod sweep every 5 minutes; all chunks present and non-zero size before join |
| S8 | Join and fps convert | Chunks joined; 25 fps converted to 30 fps with motion-blend interpolation; full-quality voice muxed onto take | Output decodes; every frame readable (truncated MP4 still has a size, so frame decode is the only reliable check) |
| S9 | Frame decode | Every frame of the joined take decoded | Zero failed frames; hard fail on any decode error |
| S10 | Compose | Director plan applied; distributed ffmpeg render with work stealing; b-roll cutaways, chapter cards, lower thirds added; audio mastered to -14 LUFS; music only first 8 and last 12 seconds; 3-second bumpers re-encoded to match body exactly (mismatched bumpers are silently dropped by ffmpeg concat); chunk-sum integrity check; deliver | Chunk-sum passes; output 1080p30; SAR 1:1 |
Lip-Sync and GPU Math
LatentSync 1.6 repaints only the mouth region. Eyes, brows, and head motion all come from the plate, which is why plate quality matters so much: one continuous recording at 1080p30, eye-contact corrected in Descript, no cuts, no black frames. We measured the following on our RTX 3090 and Vast.ai RTX 5090 pods (our data, Oct 27 2026).
- Frame size at 1080p: ~6.2 MB per frame (our data)
- 75-second chunk: ~11 GB RAM loaded before inference begins (our data)
- Peak VRAM per chunk on the RTX 3090: 21-24 GB (our data), which consumes the full card
- One 70-second chunk on the RTX 3090: ~22 minutes (our data)
- A 10-minute video is ~9 chunks; wall time ~57 minutes with 3 rented RTX 5090 pods, up to ~5 hours workstation-only (our data)
- Voice models and lip-sync can never share the 24 GB card; the binding GPU lease enforces this at the scheduler level
Pod qualification. After rent and SSH ready: measure real download speed and confirm CUDA. Hosts that fail qualification are destroyed and added to an avoid list. Listing failures throw instead of returning an empty list, a bug that once made a billing pod look like “nothing running” motivated that rule permanently.
Provider record (our data, Oct 27 2026). Across the last 10 takes, RunPod returned no capacity on all 114 attempts. Vast.ai completed all 19 successful rents. Rent hunting adds 10-20 minutes per take. Vast.ai destroy calls have silently failed before; the spend breaker and orphan sweep every 5 minutes are the backstop.
Composition and Audio
The LLM director (a larger Claude model) plans shots in 150-second windows. It draws from a catalog of 23 layouts: slide-left-Jeremy-right, chart full with bubble, b-roll full, stat card, chapter card, lower thirds, end screen, and others. Assets are sourced in order: slide panels, animated Python charts, AI images, b-roll from the tagged library, then Pexels, then Veo.
For real recordings, background matting uses RVM (Robust Video Matting) on a rented 4090: we measured ~4 minutes and ~$0.05 for a 10-minute take (our data), compared to ~70 minutes on CPU. Filler removal and Studio Sound run through the Descript API, which has no webhooks and is polled. An LLM prunes orphan lines, lines that were false starts and never completed a thought, but it never touches a line containing a number, and it never prunes more than 8% of the take.
Audio is mastered to -14 LUFS. Music plays only in the first 8 seconds and last 12 seconds. Three-second bumpers are re-encoded to match the body’s codec and frame rate exactly before concat; mismatched bumpers are silently dropped by ffmpeg concat without an error, which is how we learned this rule.
The PushPoint post-processor adds b-roll cutaways from a tagged Veo library, chapter cards, lower thirds, and stat cards that appear on the second a number is spoken (from caption timings); more than 2 seconds of drift is a hard fail; stat cards are placed only where pixel probing shows an empty zone.
The embed block is a pure function with no network or database calls. It produces a lazy responsive iframe, “key moments” chapter deep links, a collapsible timestamped transcript taken from the script (not from speech recognition), and VideoObject JSON-LD with hasPart Clip entries and SeekToAction. Old VideoObjects for the same video are removed before insert. This approach, building the page around structured video data, connects directly to what we have observed about how YouTube mentions predict AI visibility better than backlinks alone.
The Eight Publish Gates
| Gate | What it checks | Fail behaviour |
|---|---|---|
| CONTENT_GATE | No invented quotes, attributions, or case studies; claim rules; brand rules; no placeholders | Hard fail; holds for human |
| WORD_DIFF | Final audio transcribed and diffed against the script; no inserted or dropped run of 2+ words | Hard fail; holds for human |
| TITLE_BOUNDS | Title length and format within spec | Hard fail |
| ATTEST | Fail-closed process attestation: required stages ran; every render node produced its chunks; split-screen share 8-20%; b-roll on topic judged by vision tags; no retake slivers in the output | Hard fail; holds for human |
| VISUAL_REVIEW | Vision model samples frames for blank text, garbled numbers, frozen frames | Hard fail; holds for human |
| RESTATE_GATE | False-start restatements not present in final output | Hard fail |
| PROVID_QC | Plan quality including face-time share within expected band | Hard fail; holds for human |
| FRAMEVERIFY | Every frame of the final output decodes without error | Hard fail; a 54-byte MP4 is not a video; a truncated MP4 still has a size, so only frame decode is reliable |
When every gate is green, PushVid AI videos publish on autopilot up to 2 per day. One policy key turns autopilot off. Anything not green, and every real recording, waits for a WhatsApp message. Reply yes/approve/go releases it; a change note becomes fixed settings and a re-render under a new id. Publishing refuses without an approval record or an autopilot pass, refuses a second approval of the same id, and never marks a video published unless YouTube returned a video id.
Supervision and Money Controls
| Controller | Tick interval | What it does |
|---|---|---|
| Resumer | Every 5 minutes | Finds runs in pending state and calls them forward |
| Take Controller v2 | Every 2 minutes | Assigns lip-sync chunks greedily across workstation and rented pods; dispatches detached; polls; collects |
| Autodrive | Every 1 minute | Moves runs through state transitions that have a clear rule |
| Watchdog | Every 5 minutes | Detects stalled runs; escalates after 20 minutes |
| Spend breaker | Every 5 minutes | Checks GPU spend against limits (see table below); trips destroy pods and pause the resumer; overrides self-expire |
| Orphan pod sweep | Every 5 minutes | Finds pods not associated with an active run and destroys them |
| Hourly reconcile | Hourly | Reconciles cost ledger against provider billing records |
| Post-approve | Every 3 minutes | Checks for WhatsApp approval replies and releases held runs |
| Golden fixture regression | After any driver change plus nightly | Runs reference inputs through the pipeline; fails if output changes unexpectedly |
| Max (LLM operator agent) | On escalation | Handles states with no rule; capped at $3/day all-in and $1.50/run (our data) |
| Automated Claude fixer | After 3 failed tries or 20 minutes stuck | Has shell access; in 8 days: 30 jobs, $44.57, 20 fixed (~$2.20 per fix, our data); a supervision cap introduced Oct 24 cuts this share going forward |
Spend breaker limits (our data).
| Limit type | Threshold | Action on trip |
|---|---|---|
| Per take | $3 | Destroy pods; pause resumer; alert |
| Per run per day | $12 | Destroy pods; pause resumer; alert |
| Per day | $10 | Destroy pods; pause resumer; alert |
| Per hour | $8 | Destroy pods; pause resumer; alert |
| Pod-minutes | 120 | Destroy pods; pause resumer; alert |
| Provider balance floor | Per-provider minimum | Block new rents; alert |
The system’s own audit on Oct 24 counted ~22 video tickers, 7 writers to the AI run-state keys, and 7 to composition keys (our data). The planned simplification: one manager that decides, one writer per state key, ~6 tickers. The lesson we keep repeating to ourselves is one orchestrator per run, watchers that only report.
Cost Per Video
| Pipeline | Cost item | Amount (our data, Oct 27 2026) |
|---|---|---|
| PushPoint (10-min video) | ElevenLabs TTS (turbo, Pro plan) | 9:24 video = 9,022 chars = 4,511 credits = $0.74; 13:51 video ~$1.19 |
| PushPoint | LLM + 6 images | Estimated under $1 |
| PushPoint | Studio kit only | $0.14-$0.15 (16 kits = $2.39, our data) |
| PushPoint | Marginal total | ~$1-$2 per 10-minute video |
| PushVid AI | GPU (workstation to rented pods) | $0 to $2.87 per video (our data) |
| PushVid AI | Pipeline LLM | ~$0.35-$0.45 per video (our data) |
| PushVid AI | ElevenLabs TTS (~4,500 turbo credits) | Included in ~$4 production cost |
| PushVid AI | Production total | ~$4 per video |
| PushVid AI | All-in (7-day period) | $9.83/video: GPU $18.98, b-roll library $12.00, pipeline LLM $7.05, Max supervision $21.36, Claude fixes $38.96; supervision and fixing were 61% of total (our data) |
| PushVid real recording | Matting (RVM on rented 4090) | ~$0.05 per 10-minute take (our data) |
| PushVid real recording | Veo b-roll via fal | ~$0.10/second, capped $6/video (our data) |
| PushVid real recording | Total | Under $1 plus b-roll |
The all-in figure for PushVid AI shows where the actual cost pressure lives: not in GPU or TTS, but in automated supervision and repair. The deeper analysis of those trade-offs is in our lessons and cost breakdown from building this pipeline. The supervision cap introduced Oct 24 is already cutting the Max and fixer share for subsequent runs.
Data Model (Short)
The Brain table is a key-value store with history: every write keeps the previous value, so any key can be read at any point in time. Drivers, config, per-run state, and logs all live here. Relational tables alongside it cover: job log; call audit; consumers and rate limits; schedules; PushPoint topic queue (queued, claimed, done, parked, blocked, superseded, failed); publish-window queue; video queue and LinkedIn queue; video registry (format: slideshow, ai_avatar, real); own videos with pre/post measurement windows; kits; locks, GPU leases, heartbeats, and stage timings; intake and Descript poll state; client decks and channel uploads; tagged b-roll library with use counts; publish locks (asset key plus platform, to prevent double-publish); cost ledger; API costs; changelog; alerts.
Every external write is idempotent behind a publish lock and verified by reading it back. Every shipped change gets a changelog row. This structure is what lets the resumable state machine work: there is always a single authoritative record of where a run is, and nothing writes to it except the designated owner driver. The approach to auto-publishing to WordPress is built on the same idempotent read-back-verify pattern.
Known Weak Spots
- Real intake regression: passed 0 of 10 times in the last 7 days (our data); the least reliable part of the system
- Mid-word restarts: not yet cut automatically; the filler-removal pipeline handles false starts at the sentence level but not within a word
- Shot plan non-determinism: face-time share varies run to run because the shot plan is not seeded deterministically; the same script can produce different layouts on re-run
- GPU supply: across the last 10 takes, RunPod returned no capacity on 114 consecutive attempts (our data); Vast.ai destroy calls have silently failed before; the breaker and orphan sweep are the only backstops
- Too many controllers: the Oct 24 audit counted ~22 video tickers and 7 writers to a single state key (our data); this is the root cause of most stall and double-action bugs
- Mouth composite retries: failed lip-sync chunks are relaunched by index, but there is no automatic retry at the composite level; a human must intervene if a chunk fails after the retry ladder
- Long job cancellation: jobs are cancelled on 15-minute wall-clock boundaries by a mechanism not yet fully identified; workaround is to keep detached work short and poll
- Workstation availability: the RTX 3090 is shared with Jeremy’s own use; a policy key controls rendering, but unplanned workstation use can block a run for hours
Lessons a Rebuild Should Keep
These are the rules we had to learn by breaking them. Each one corresponds to a real failure in the running system.
- One TTS job per voice section; one narration segment per slide. Never synthesize a whole script and align afterwards. A single cut would desync every subsequent slide or section permanently.
- Transcribe generated audio and diff per section. Per-sentence checks miss defects that land on sentence boundaries. The diff must operate at the section level with normalised text in both cardinal and digit modes.
- Check file size and decode every frame. A 54-byte MP4 is not a video. A truncated MP4 still has a non-zero file size. Frame-by-frame decode is the only check that catches truncation reliably.
- Probe sample aspect ratio, codec, fps, and audio parameters before concatenation. Mismatched segments are silently dropped by ffmpeg concat without an error. This is how bumpers disappeared for several weeks before we traced the cause.
- Never default a failed remote listing to an empty list before a safety decision. An API change once made a billing GPU pod look like “nothing running.” Listing failures must throw, not return empty.
- Run gates before the expensive step. Claim gate before TTS; plan gate before lip-sync. Gates must fail closed, not open.
- Every external write is idempotent and verified by reading it back. YouTube, WordPress, LinkedIn: write once behind a publish lock, then read the result back. Never mark published unless the platform returned an id.
- One orchestrator per run; one writer per state key; watchers only report. The current system has 7 writers to a single run-state key. Every ambiguity in ownership creates a class of stall bugs that no amount of watchdog logic can fully prevent.
- Budgets per take, per run, per day, and per hour with self-expiring overrides. A single breaker at the day level is not enough. GPU spend can spike within an hour in ways that a daily cap does not catch until damage is done.
- Seed any choice that must be stable across resumes. The PushPoint format variant uses an FNV-1a hash of the slug so a resumed run always picks the same variant. Any random choice in a resumable pipeline needs a stable seed or it becomes a new pipeline on each resume.
- Re-encode bumpers to match body parameters exactly. Three-second intro and outro clips look identical in a file browser but carry different timebase, codec profile, or audio channel count. ffmpeg concat drops them silently.
- Keep driver touches per delivered kit as low as possible. In the last 7 days we averaged 3.1 touches per delivered kit (our data). A product version of this system should eliminate live driver edits during runs entirely.
Module Map for a Rebuilt Application
| Module | Responsibility | Key design constraint |
|---|---|---|
| Durable workflow engine | Resumable steps, retries classified by failure type, timers | One orchestrator per run; state in one key; no external writers |
| Tenant and lane config | Per-client voice, YouTube token, privacy default, approver, publish days, videos per week, brand rules | Form-driven, not code forks; brand facts validated at setup not at render time |
| Content services | Topic scoring, page writer, kit writer, page matcher | Page matcher confidence under 0.6 counts as no match; kit writer uses the matched page as the only fact source |
| Media workers | Deck render, TTS, slideshow assembly, composition render | All workers idempotent; skip-if-artefact-exists; one retry per failure class |
| GPU job service | Provider adapters (Vast.ai, RunPod, local), leases, qualification, budgets | Provider pool with fallback or a hosted lip-sync API; listing failures throw; spend breaker at take/run/day/hour; orphan sweep on a timer |
| Gate library | All eight publish gates plus in-pipeline checks (claim gate, plan gate, frame decode) | Pure functions; fail closed; verdicts recorded in the run record |
| Publish adapters | YouTube, WordPress, LinkedIn, Google Drive | Write idempotent behind publish lock keyed on asset plus platform; verify by read-back; never mark published without platform id |
| Approvals and notifications | WhatsApp (Twilio); dashboard alerts; hold and release state transitions | One approval record per video id; refuse second approval of same id; post-approve polling every 3 minutes |
| Cost ledger and measurement | Per-call cost recording; pre/post Search Console windows; weekly AI-citation prompts | Hard spend limits checked before any paid step; ledger reconciled against provider billing hourly |
| Admin UI | Run heartbeats, locks, items needing a human, costs, alerts; one-click actions for “needs attention” states | Bounded retry then “needs attention” with a one-click action; no live code edits from UI; versioned deploys only |
| CI and regression | Reference-video regression before each release; golden fixture nightly | Must run before any deploy; fail blocks the deploy; 52 drivers edited in one week is the failure mode this prevents |
The content this pipeline produces, structured, entity-rich video pages with VideoObject schema, is designed to be readable by both humans and AI systems. That connection between technical pipeline design and AI search visibility is something we examine in depth in our research on whether YouTube videos get cited in AI search answers and in the follow-up on how different video formats perform in AI citations. The pipeline’s insistence on a real transcript (from the script, not speech recognition) and structured chapter data in SeekToAction is a direct product of what those citation patterns showed us. For operators thinking about content publishing automation workflows at scale, the data model and gate library here represent the minimum viable infrastructure for a system that can run without a human watching every output.
Sources
- All technical facts, numbers, and stage details: PushLeads internal technical documentation, dated October 27, 2026 (our data)
- PushLeads guide to the PushVid AI video pipeline
- Incredible Roots: lessons and costs from building the AI video pipeline
- Why YouTube Mentions Now Predict AI Visibility Better Than Backlinks
- Auto Publish to WordPress SEO: Scale Content Without Manual Work
- Do YouTube Videos Get Cited in AI Search? What Our Channel Showed in October 2026
- We Undercounted Our AI Video Citations: A Follow-Up on Slideshows, AI Avatars and Real Presenters
- Content Publishing Automation Workflows for Agencies: A Practical Guide for 2025